I am a PhD student at the School of Computing and Data
Science, University of Hong Kong, advised by Prof. Dong Xu,
and have worked with Prof. Difan Zou. Previously, I received my bachelor's degree from
Shanghai Jiao Tong University in 2022, where I studied control science and engineering.
I am currently working on empowering agents to learn from
play (suboptimal trajectories) without hand-crafted
extrinsic rewards and to adapt in few/zero shot. I have also
done research on bridging the gap and revealing the
connections between energy-based learning and practical
Transformer design.
I favor research grounded in and motivated by fundamental principles over empirical heuristics,
and I enjoy exploring seemingly unrelated connections across different fields and challenging the conventional wisdom.
@misc{hu2026vpflow,
  title={VPFlow: Value-Predictive Planning with Imperfect World Models for Offline Goal Reaching},
  author={Yunzhe Hu and Dong Xu},
  year={2026},
  eprint={2610.27280},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2610.27280}
}
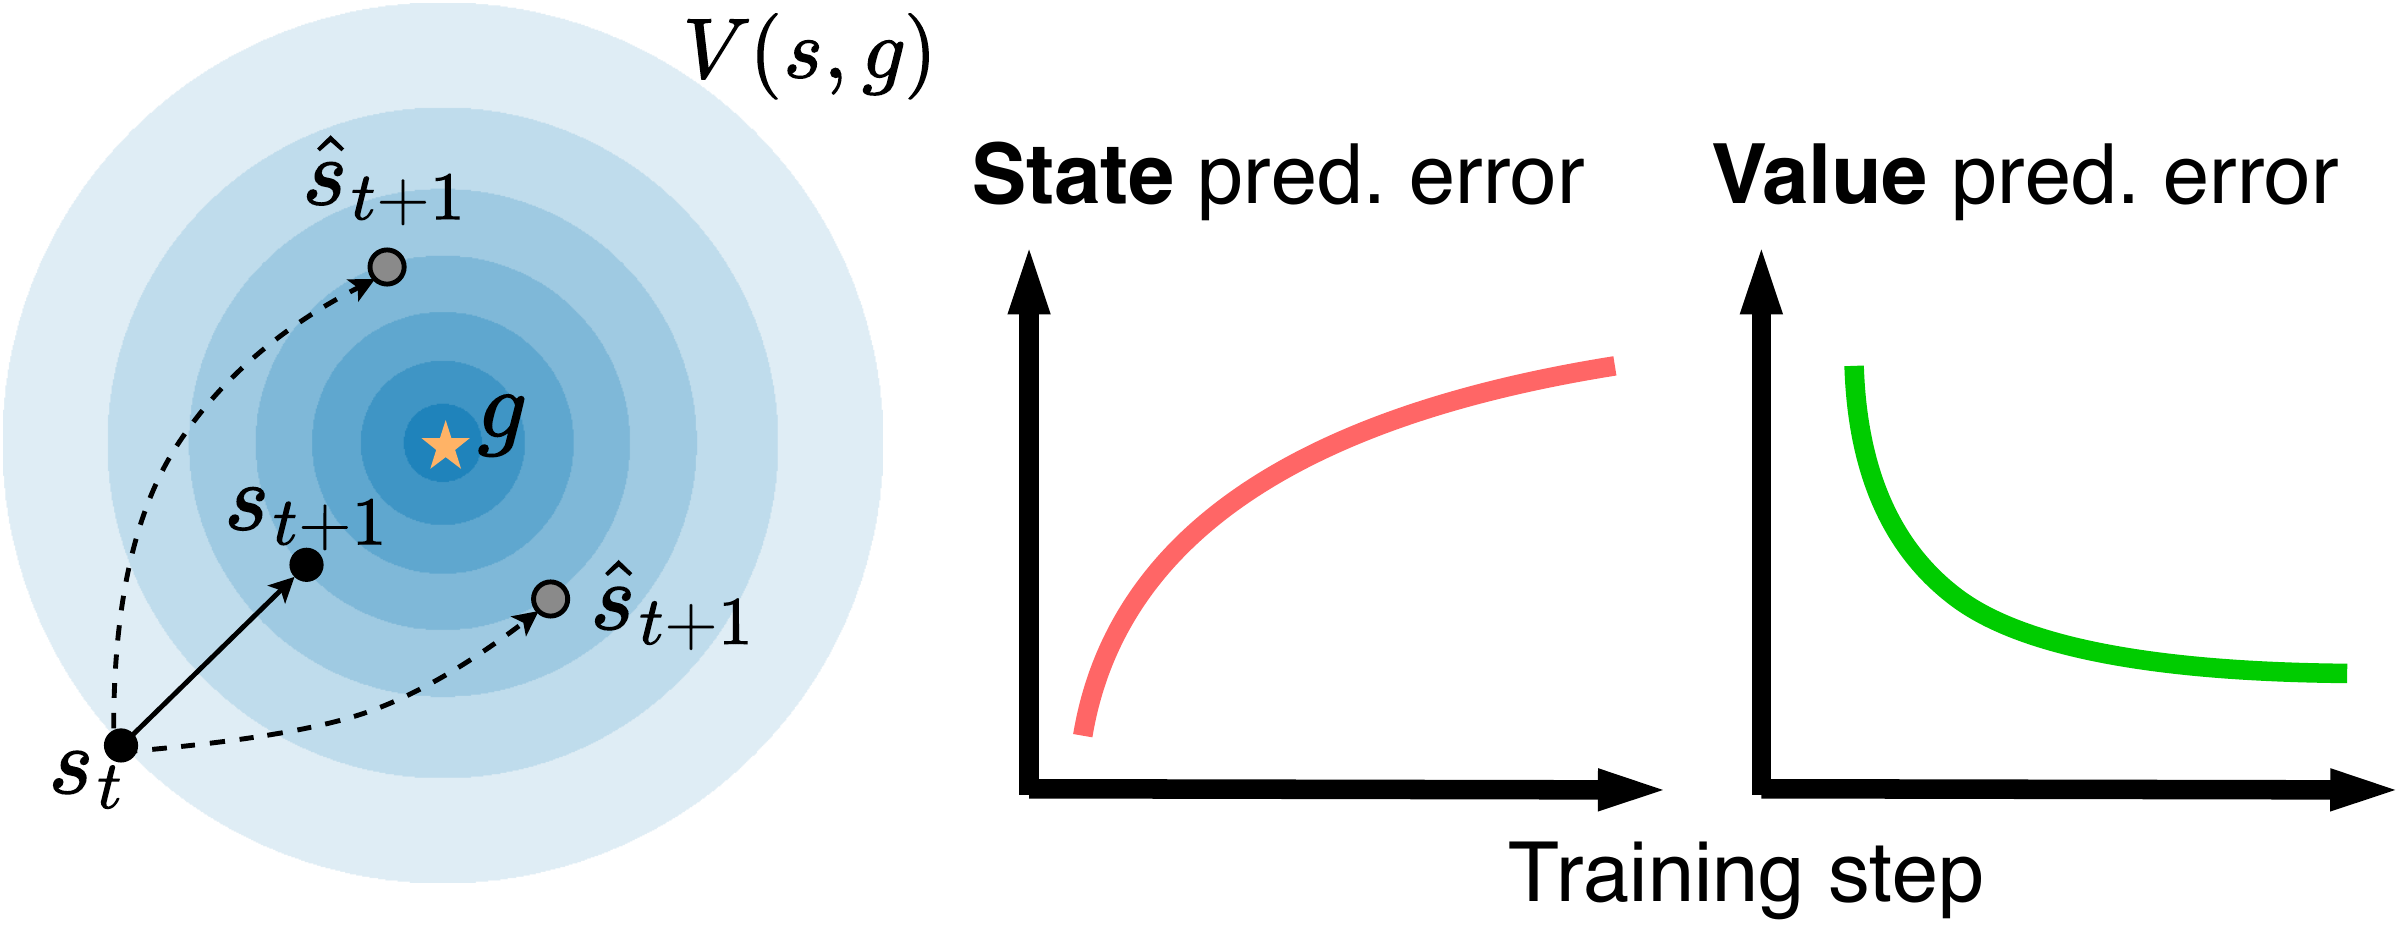
A value-predictive planner for offline goal reaching:
world models are trained to predict goal-reaching values rather than
latent states, while noise-space planning enables policy improvement with imagined advantage without OOD queries.
It challenges the pervasive assumption of next-state prediction in world models,
showing that value prediction is more useful for planning, whereas accurate state prediction is often unnecessary.
@inproceedings{
  hu2026hyperset,
  title={Hyper-{SET}: Designing Transformers via Hyperspherical Energy Minimization},
  author={Yunzhe Hu and Difan Zou and Dong Xu},
  booktitle={The Fourteenth International Conference on Learning Representations},
  year={2026},
  url={https://openreview.net/forum?id=FinhjyDgYA}
}
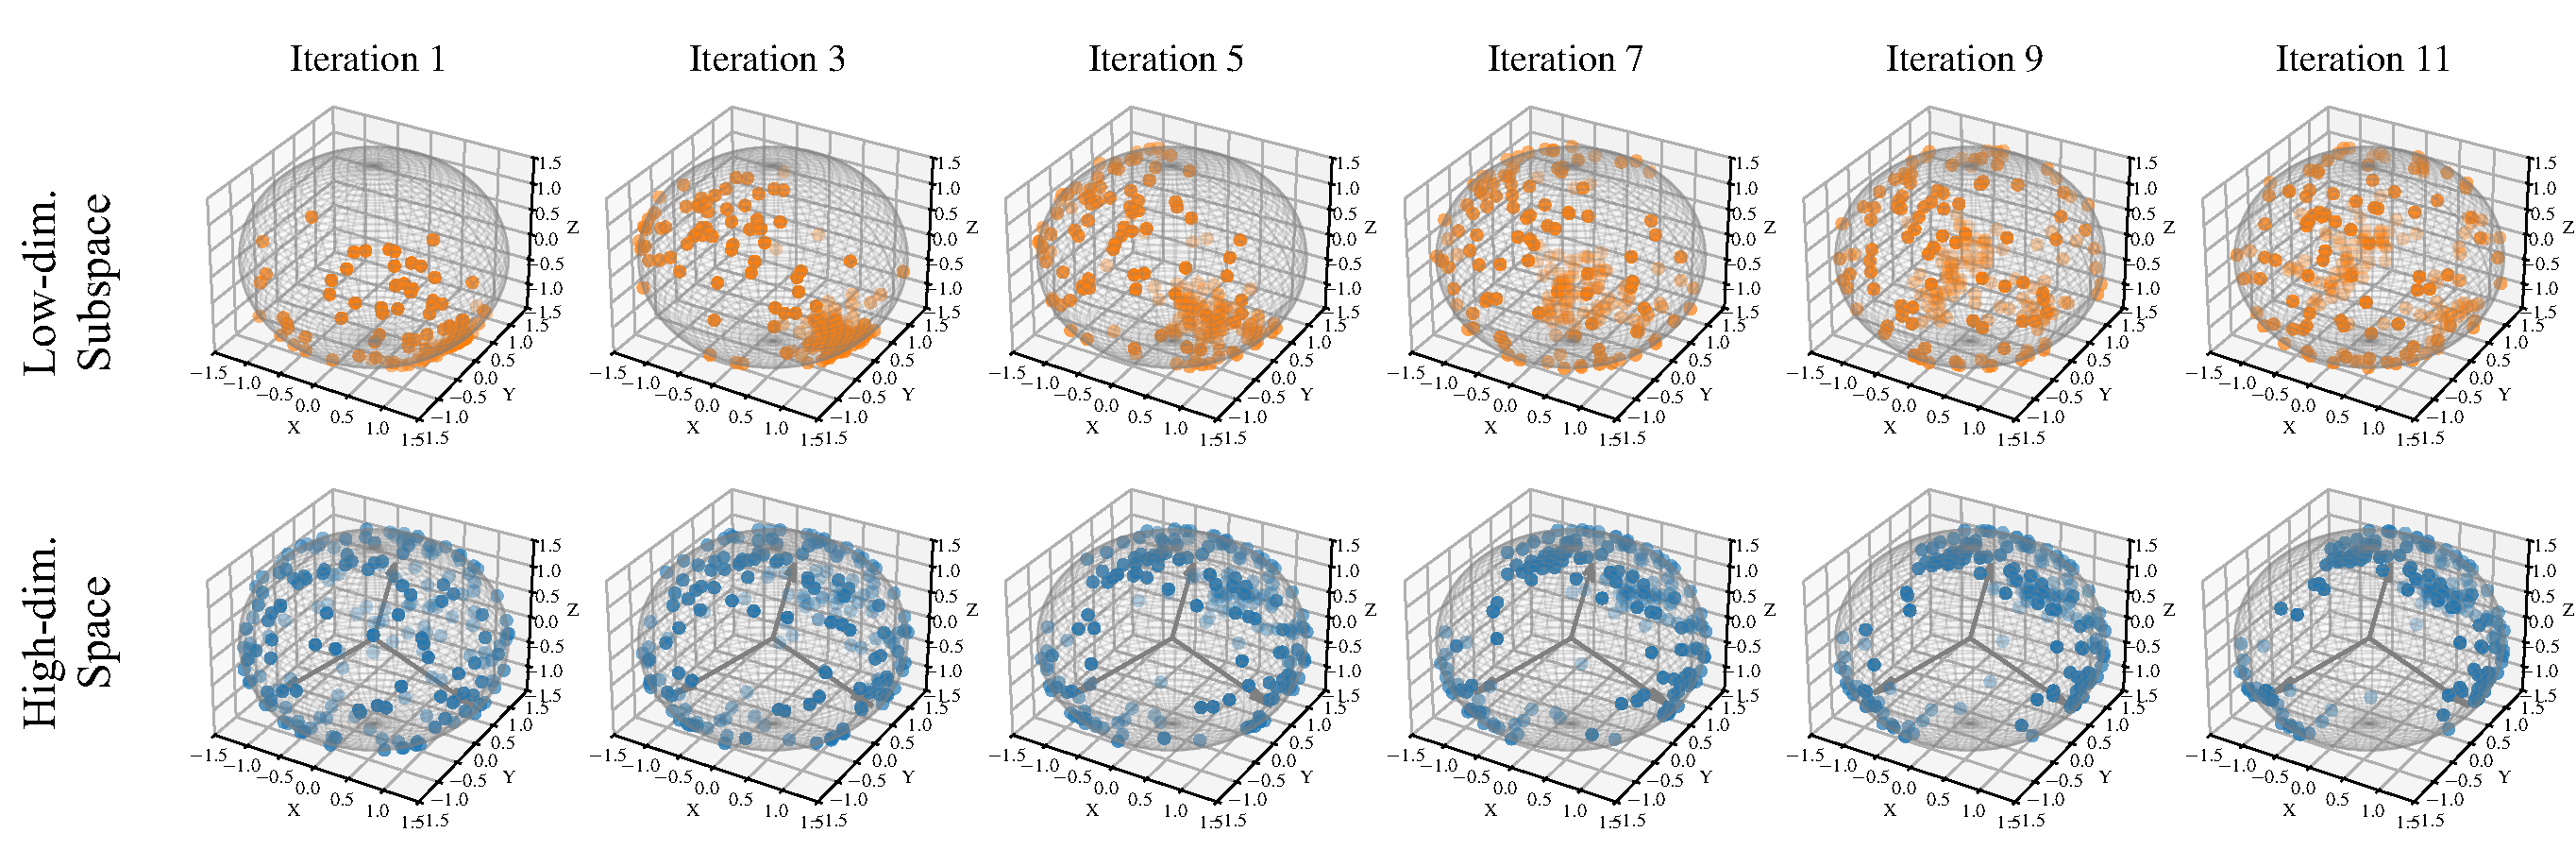
A principled, top-down Transformer design grounded in
energy-based interpretation: symmetric attention,
feedforward, and RMS normalization all emerge from
iterative constrained energy minimization on the
hypersphere, yielding a compact recurrent-depth model
competitive across reasoning, classification, and masked
modeling tasks.
@inproceedings{
  hu2024an,
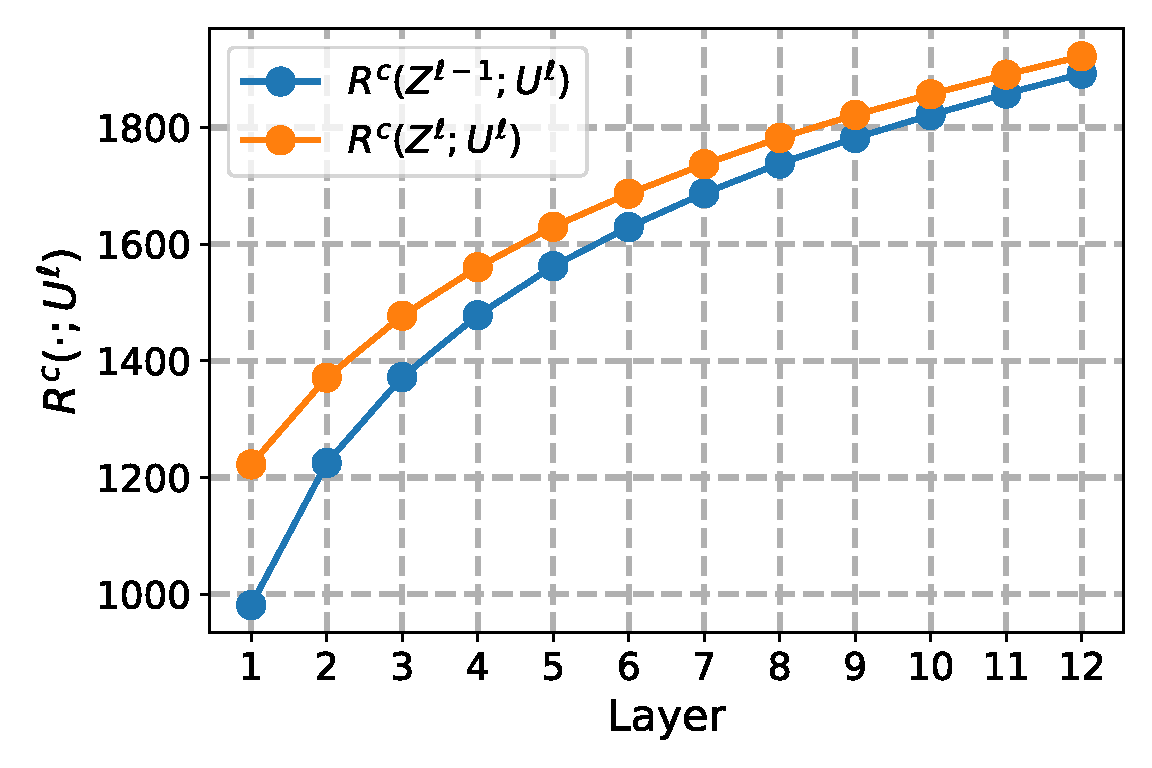
  title={An In-depth Investigation of Sparse Rate Reduction in Transformer-like Models},
  author={Yunzhe Hu and Difan Zou and Dong Xu},
  booktitle={The Thirty-eighth Annual Conference on Neural Information Processing Systems},
  year={2024},
  url={https://openreview.net/forum?id=CAC74VuMWX}
}